
STATUS IS UPWEBSITE OPTIMIZATION WIKI
29Harden
SEO and discoverability / Harden

Technical SEO Audit: A Practical Owner’s Guide

A practical, evidence-led audit for finding technical barriers to search discovery and reducing the chance they return.

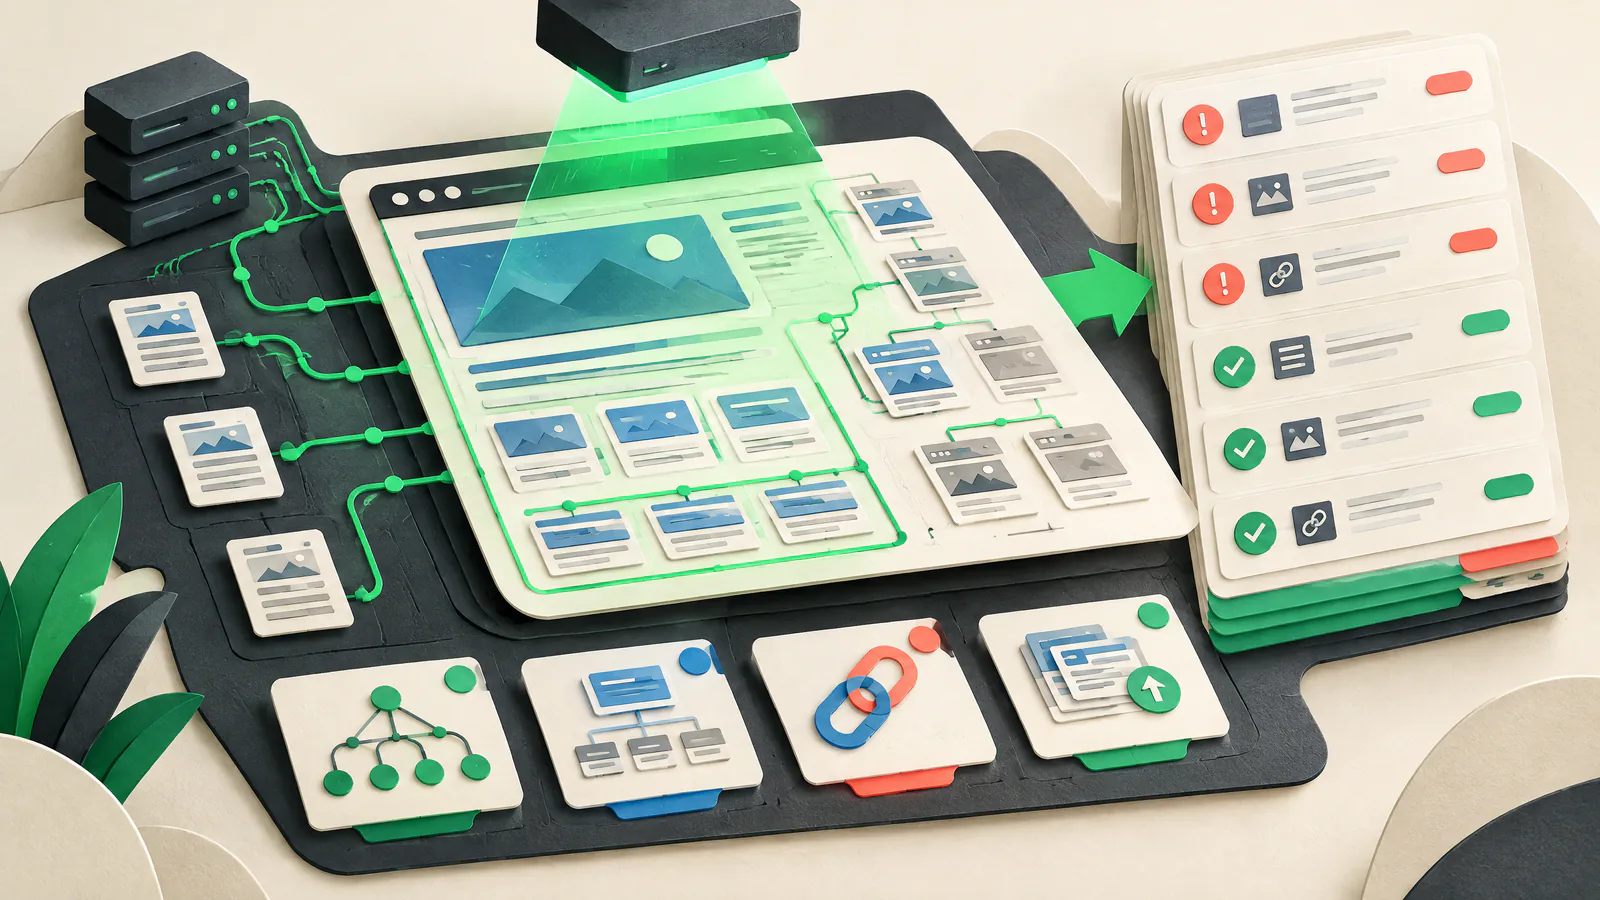
Technical SEO Audit: A Practical Owner’s Guide — VISUAL GUIDE
READ
8 minutes
SOURCES
6
REVALIDATE
2027-03-27
reviewed
Technical SEO and web platform reviewer
THE SHORT ANSWER

Start with the decision.

Run a technical SEO audit as a short evidence loop: decide which public pages should be found, test their response and final URL, check index controls and canonical signals, compare source with rendered content, then reconcile links and sitemaps. Fix the highest-impact pattern first, and re-test after release.

Put blockers before scorecards. An unintended noindex, server error, incorrect redirect, conflicting canonical, or missing rendered content can stop a valuable page being considered for indexing. A 200 response is only an opportunity for processing, not a guarantee of indexing or rankings.

Keep the deliverable operational: affected pattern, expected behavior, proof, owner, rollout plan, and rollback path. Status Is UP supports proactive uptime optimization and remediation so important pages remain reliably reachable and complete; it is not live-status monitoring or a promise about search-engine outcomes.

VISUAL GUIDE

See the work as a system.

Use this map to connect the article’s decisions before acting on individual tactics.

SIUHarden
01Start with intended pages and reusable evidence
02Make indexability a deliberate decision
03Make one preferred URL consistent
04Check status codes and redirect behavior
01

Start with intended pages and reusable evidence

List the public pages you want searchers to find: key products, articles, categories, and moved URLs. For each, record the preferred URL, expected response, indexability, template, owner, and priority. Keep legitimate exclusions separate.

Capture an unauthenticated response, headers, redirect path, page source, rendered view, internal-link state, and sitemap state for representative URLs. Sample every template and URL pattern. Evidence is dated: a CDN setting, deployment, consent layer, or personalization can change it later.

Test patterns

A passing homepage does not prove that listings, product variants, or localized routes work.

Save a baseline

Keep dated headers and rendered evidence so fixes and later regressions can be compared.

02

Make indexability a deliberate decision

Indexability means a page may be included in a search index; it is not the same as crawling or ranking. Check meta robots directives in HTML and X-Robots-Tag response headers. The noindex directive tells search engines not to show a page; X-Robots-Tag also applies to non-HTML files such as PDFs.

Review robots.txt separately. A crawler must access a page to find its noindex directive, so blocking that URL can prevent the directive being seen. Check the deployed, public response because CMS settings and environment flags can add rules. Noindex is not access control: protect sensitive material with authentication and appropriate security review.

Find accidental exclusions

Flag noindex, login responses, staging references, and blocked essential assets on intended-index pages.

Check headers too

An HTTP response header can carry a directive even where no HTML head exists.

03

Make one preferred URL consistent

Canonicalization identifies the preferred URL among duplicate or very similar versions, such as HTTP and HTTPS, hosts, tracking parameters, filters, or print pages. Compare the canonical element, internal links, sitemap URL, and redirect destination. For an indexable page, they should normally identify the same absolute preferred URL.

Use a permanent server-side redirect when retiring a duplicate. Google describes permanent redirects and rel=canonical as strong signals, while sitemap inclusion is weaker; aligned signals reinforce the preference. Do not use robots.txt to canonicalize or give one page competing canonicals. A self-referencing canonical helps state the preferred version, but search-engine selection remains outside your control.

Map each family

Document variants, the preferred target, the required control, and an owner.

Protect changes

Test old-to-new mappings before a migration and keep a reversible redirect change ready.

04

Check status codes and redirect behavior

Status codes tell browsers and crawlers what happened. Important live pages should return a meaningful 2xx response with intended content. A page with no relevant replacement should return a genuine 404 or 410; moved content should reach its closest relevant replacement. A 200 page that only shows an error may be treated as a soft 404.

Record every redirect hop. Google generally follows up to 10 hops for general web crawling, but chains add latency and fragility. Google says 5xx and 429 responses can temporarily slow crawling and persistent server errors can ultimately remove indexed URLs. Investigate recurring failures with the engineering owner across application, CDN, origin, cache, dependency, and deployment layers.

Classify outcomes

Save original URL, hops, codes, final URL and expected state.

Fix the rule set

Remove overlapping CMS, CDN, host, locale, or slash rules instead of adding another hop.

05

Validate JavaScript rendering and routes

Inspect both the initial HTML and a rendered view for key templates. Confirm the main content, headings, links, canonical, robots directives, and state exist after rendering. Google describes separate crawl, render, and index phases and says content not visible in rendered HTML cannot be indexed.

Use anchor elements with href values for navigation. Fragment-only routes that load distinct content are not reliable for discovery. Directly request nonexistent products, articles, and filtered URLs. Client-side applications need a real error state; Google documents routing to a server 404 or adding noindex to avoid soft 404s. Server rendering or prerendering can help, but verify the deployed response.

Compare three views

Check response HTML, rendered HTML, and the human browser view for material differences.

Keep canonical stable

Prefer source HTML; if JavaScript sets it, ensure there is one non-conflicting canonical.

06

Keep sitemaps and internal links clean

A sitemap is a discovery map, not an indexing command. Include successful, intended, preferred canonical URLs; exclude redirects, errors, noindex pages, parameter duplicates, and protected URLs. Google recommends fully qualified absolute URLs and treats sitemap inclusion as a canonical hint, not a guarantee.

Validate the sitemap and compare it with the intended-index list and navigation. Google documents UTF-8 encoding and a limit of 50 MB uncompressed or 50,000 URLs per sitemap. For larger sites, split into useful groups and use an index. Update lastmod only for significant, verifiable page changes.

Reconcile lists

Investigate meaningful differences between intended URLs, sitemap entries, and internal links.

Re-fetch after release

Check the generated sitemap and a sample of listed URLs after routing or CMS changes.

07

Measure performance and institutionalize the audit

Use field data where available and controlled lab testing to investigate Core Web Vitals: Largest Contentful Paint for loading, Interaction to Next Paint for responsiveness, and Cumulative Layout Shift for visual stability. Segment by page type and device because averages can hide a broken high-value template.

Trace slow or unstable delivery through images, CSS and JavaScript, third-party tags, fonts, embeds, and caching. Make one measured change, then recheck rendering and user flows. Field data reflects real users; lab data aids reproduction. Neither predicts every future crawler or visitor. Repeat a focused regression check after risky releases and a fuller audit after migrations or platform changes.

Prioritize exposure

Repair failures on revenue-critical or heavily used templates before small score gains elsewhere.

Close with proof

Recheck response, canonical, rendered content, sitemap state, and relevant performance evidence before closing.

ACTION / VERIFY

Your practical to-do guide.

  1. 01

    Set the intended-index inventory

    List key public URLs by template with expected canonical, indexability, priority, and owner.

    VERIFY: Every major template has a sampled, documented expected state.
  2. 02

    Record public responses

    Capture status, headers, redirect hops, final URL, and content type without a logged-in session.

    VERIFY: No sampled important URL has an unexplained chain or server error.
  3. 03

    Review index controls

    Check robots meta, X-Robots-Tag, and robots.txt accessibility.

    VERIFY: Intended-index pages have no accidental exclusion and sensitive pages use access controls.
  4. 04

    Reconcile canonical signals

    Compare canonical tags, redirects, internal links, sitemaps, host, and HTTPS choices.

    VERIFY: Each duplicate family has one documented preferred URL or a written exception.
  5. 05

    Exercise failures and moves

    Request old, nonexistent, HTTP, alternate-host, and removed-content URLs.

    VERIFY: Moves are direct and relevant; missing content does not return a 200 error shell.
  6. 06

    Inspect rendering

    Compare source and rendered output for text, links, metadata, and error routes.

    VERIFY: Essential content and crawlable links are visible after rendering.
  7. 07

    Validate sitemap and links

    Compare the sitemap, intended-index list, and internal navigation.

    VERIFY: Only successful preferred URLs intended for discovery are listed.
  8. 08

    Measure by page type

    Review field and lab performance evidence, including dependencies and assets.

    VERIFY: Every performance fix names affected template, evidence, and regression checks.
  9. 09

    Release safely and retest

    Ship grouped fixes with a rollback plan, then repeat the affected checks.

    VERIFY: Closed high-priority work has before-and-after evidence.
DISCUSSION TOPICS

Compare the trade-offs, not private data.

Use these prompts with your team or website-owner community. Share methods and lessons, but never paste credentials, customer records, or non-public infrastructure details.

  1. 01

    Which URL pattern caused your most widespread technical discovery problem, and what evidence revealed the shared cause?

  2. 02

    How do you decide whether a duplicate should redirect, declare a canonical, stay accessible, or be excluded?

  3. 03

    Which release check best catches rendering, sitemap, or response regressions before they reach important pages?

POPULAR / AUTHORITATIVE RESOURCES

Open the source material.

Google Search CentralHow to specify a canonical URL with rel=canonical and other methods ↗

Canonical signals, redirects, self-referencing canonicals, and conflicts to avoid.

Reviewed 2026-09-27
Google Search CentralUnderstand the JavaScript SEO basics ↗

Crawl, render, routes, canonical injection, and soft 404 guidance for JavaScript applications.

Reviewed 2026-09-27
Google for DevelopersHow HTTP status codes affect Google’s crawlers ↗

A reference for 2xx, redirects, 4xx, 429, and 5xx crawler handling.

Reviewed 2026-09-27
Google Search CentralBuild and submit a sitemap ↗

Sitemap URL selection, limits, lastmod, and submission caveats.

Reviewed 2026-09-27
Google Search CentralRobots meta tag, data-nosnippet, and X-Robots-Tag specifications ↗

Index directives, headers for non-HTML files, and crawling versus noindex.

Reviewed 2026-09-27
web.devLearn Core Web Vitals ↗

Resources for core experience metrics.

Reviewed 2026-09-27

Source policy. Based on official Google Search Central, Google for Developers, and web.dev pages read on the access date. Documented crawler behavior is distinguished from practical recommendations; indexing and rankings are not promised.

QUICK CLARIFICATIONS

Common questions.

How often should I run a technical SEO audit?

Run focused regression checks after changes to templates, routing, CMS, CDN, tags, or dependencies. Run a fuller audit after a migration, redesign, platform change, or major URL work. Match frequency to change risk and business importance.

Does a 200 status code mean a page will rank or be indexed?

No. A 200 response allows processing, but does not guarantee indexing or rankings. Index controls, canonical consistency, accessible useful content, and search-engine evaluation still matter.

Should I block duplicate pages in robots.txt?

Usually no. Robots.txt is not canonicalization, and blocking can prevent discovery of a noindex directive. Align the preferred URL, redirects, canonical signal, internal links, and sitemap instead; use access controls for sensitive content.

Status Is UP Editorial Team · Uptime Enablement Editors

Reviewed by Technical SEO and web platform reviewer. Published 2026-09-27; updated 2026-09-30.