
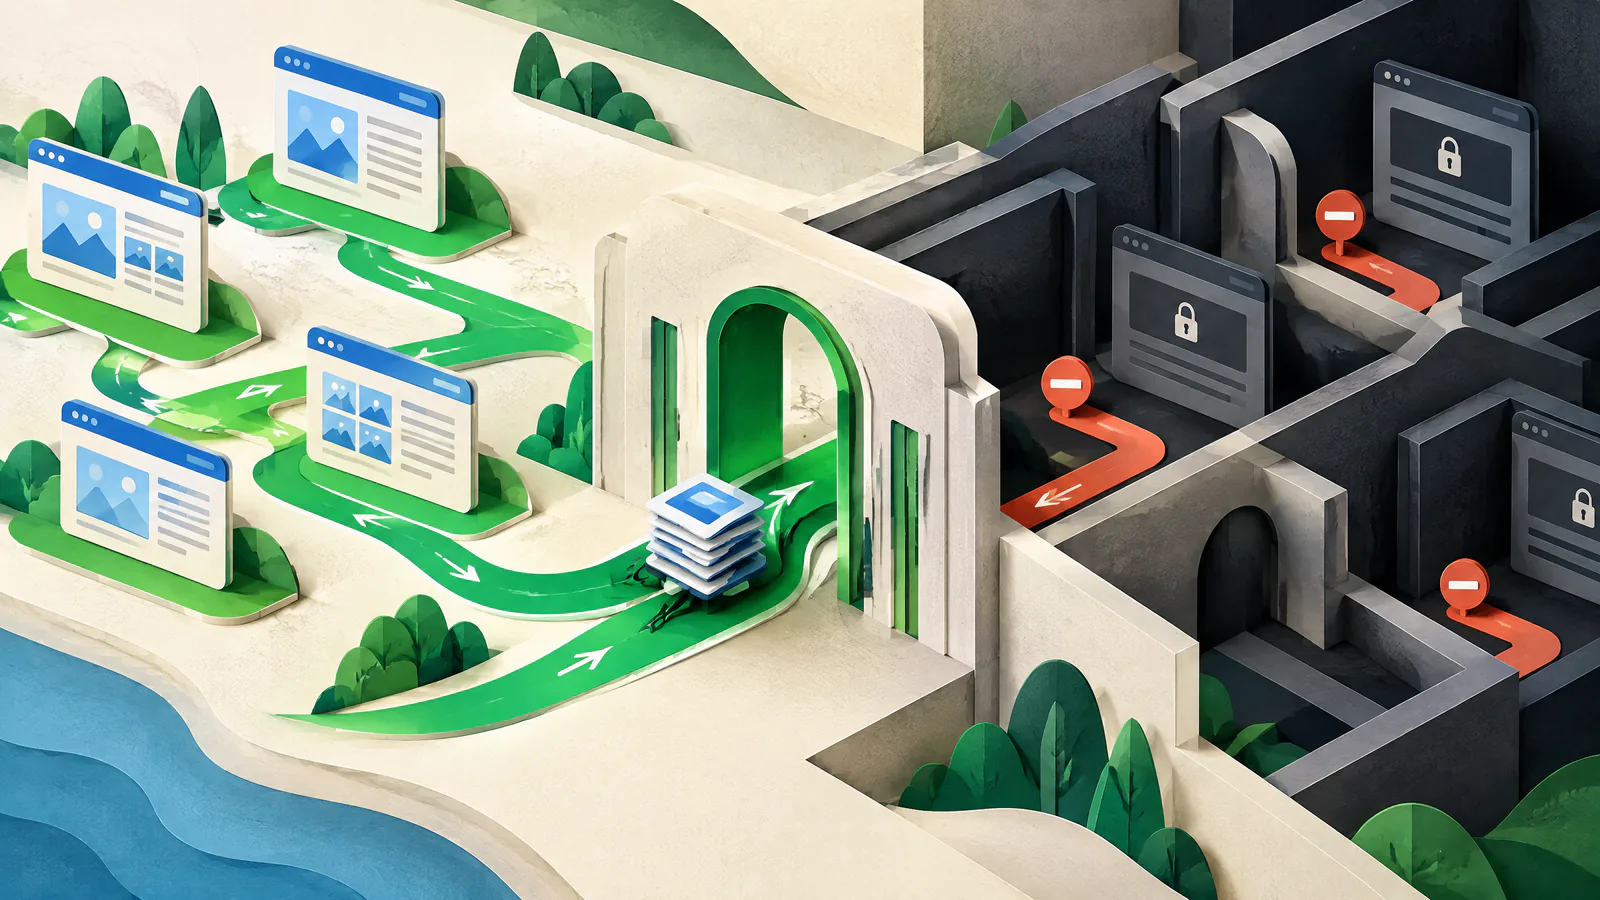
Choose the control that matches the outcome
Crawling is automated retrieval of a URL. Indexing is a search engine deciding whether to store and show information about it. Access control decides who can obtain content. Robots.txt concerns crawling, and compliant crawlers choose whether to follow it. The IETF Robots Exclusion Protocol says it is not authorization.
Use a Disallow rule to manage crawler access to a public, low-value path, such as a controlled internal-search route. Use noindex for public content that should not appear in supported search results. Use real access controls for previews, account areas, exports, or sensitive data. For customer, employee, payment, or regulated information, obtain qualified security and platform review; robots.txt is never a compensating control.
Robots.txt can request that compliant crawlers avoid a defined public path; it does not guarantee removal from results.
Use noindex in HTML or an X-Robots-Tag header, and leave the response crawlable so the instruction can be read.
Require authentication or an appropriate application or server control, then remove the URL from public discovery paths.
Use the core syntax and scope precisely
Publish UTF-8 plain-text robots.txt at /robots.txt for each scheme, host, and port that needs rules. A file at https://www.example.com/robots.txt does not automatically govern https://example.com, a subdomain, or an HTTP origin. Verify the origins served by canonical URLs, redirects, CDN, and application before assuming a rule applies.
A group starts with User-agent and then uses Allow or Disallow paths. User-agent: * is the general group. Matching is case-sensitive and starts at the path beginning. The most specific matching rule wins; an equally specific Allow should win over Disallow. Disallow: blocks nothing, whereas Disallow: / blocks the entire origin. The standard defines # for comments, * for wildcard, and $ for the end of a pattern.
If there is no documented crawl-management need, add no exclusions; do not create speculative blocks.
Prefer a stable, narrow prefix such as /search/ over a loose wildcard or an unexplained filename rule.
Record the rule purpose, owner, and change reference, but do not treat comments as a substitute for review.
Block only patterns supported by URL evidence
Before writing a rule, inventory important pages, unwanted crawl paths, query variants, on-site search, preview routes, assets, and sitemap URLs. For each sample URL, record the expected result and matching rule. Compare the list with canonical URLs and live navigation so a block does not hide a useful route.
Keep browser-critical resources available unless tested otherwise. Google cautions that blocking CSS, JavaScript, images, or other resources can make a page harder to analyze. Robots.txt does not solve duplicate-content selection, authorization, or page quality; use canonicalization, redirects, access controls, or content work where appropriate.
Use real URL samples and server or crawl evidence, not a generic list copied from another site.
Keep each sample URL, intended result, matched rule, and accountable owner in the release record.
Keep sitemap discovery, noindex, and privacy decisions consistent
A sitemap tells search engines which URLs and files you consider important; it can help discovery but does not guarantee crawling or indexing. Strong internal links still matter. You may add a fully qualified Sitemap URL in robots.txt, but do not list private, redirected, robots-blocked, or intentionally noindex URLs. Reconcile sitemap output with robots rules at release.
Noindex is not a Google robots.txt directive. Google supports it in an HTML meta tag or X-Robots-Tag HTTP response header, and must crawl the response to see it. If a public page needs to leave Google results, remove any robots block that hides noindex. If content is nonpublic, do not advertise its path in robots.txt; enforce access control. Sensitive-data boundaries need qualified review.
Use a full URL, for example Sitemap: https://www.example.com/sitemap.xml; it does not override a crawl block.
Use a meta noindex for HTML or an X-Robots-Tag: noindex response header where suitable, then test the live response.
Restrict access first when content is sensitive, then use the search engine’s removal process where appropriate.
Test and release it like a critical configuration file
Validate the approved text locally, then test allowed and disallowed examples for the intended crawler group. After deployment, retrieve public /robots.txt privately or by direct HTTP request to confirm the content, origin, and response status. Google offers a Search Console robots.txt report for accessible files and an open-source parser library for local testing.
Crawlers can cache robots files, so do not promise immediate discovery or indexing changes. Server or network errors lead crawlers to assume complete disallow, while a 4xx may permit access. Keep the file in source-controlled configuration, require extra review for whole-site or wildcard changes, and retain the prior version. SIU preflights and rollback planning help catch a bad release before it becomes a larger availability or discoverability problem.
Require a second reviewer for origin migrations, whole-site blocks, wildcards, and changes affecting sign-in, checkout, or support routes.
Restore the prior version when an important sample URL is newly blocked, a necessary asset is inaccessible, or the endpoint is unavailable.
One crawler test does not prove that every automated client interprets every rule in the same way.